

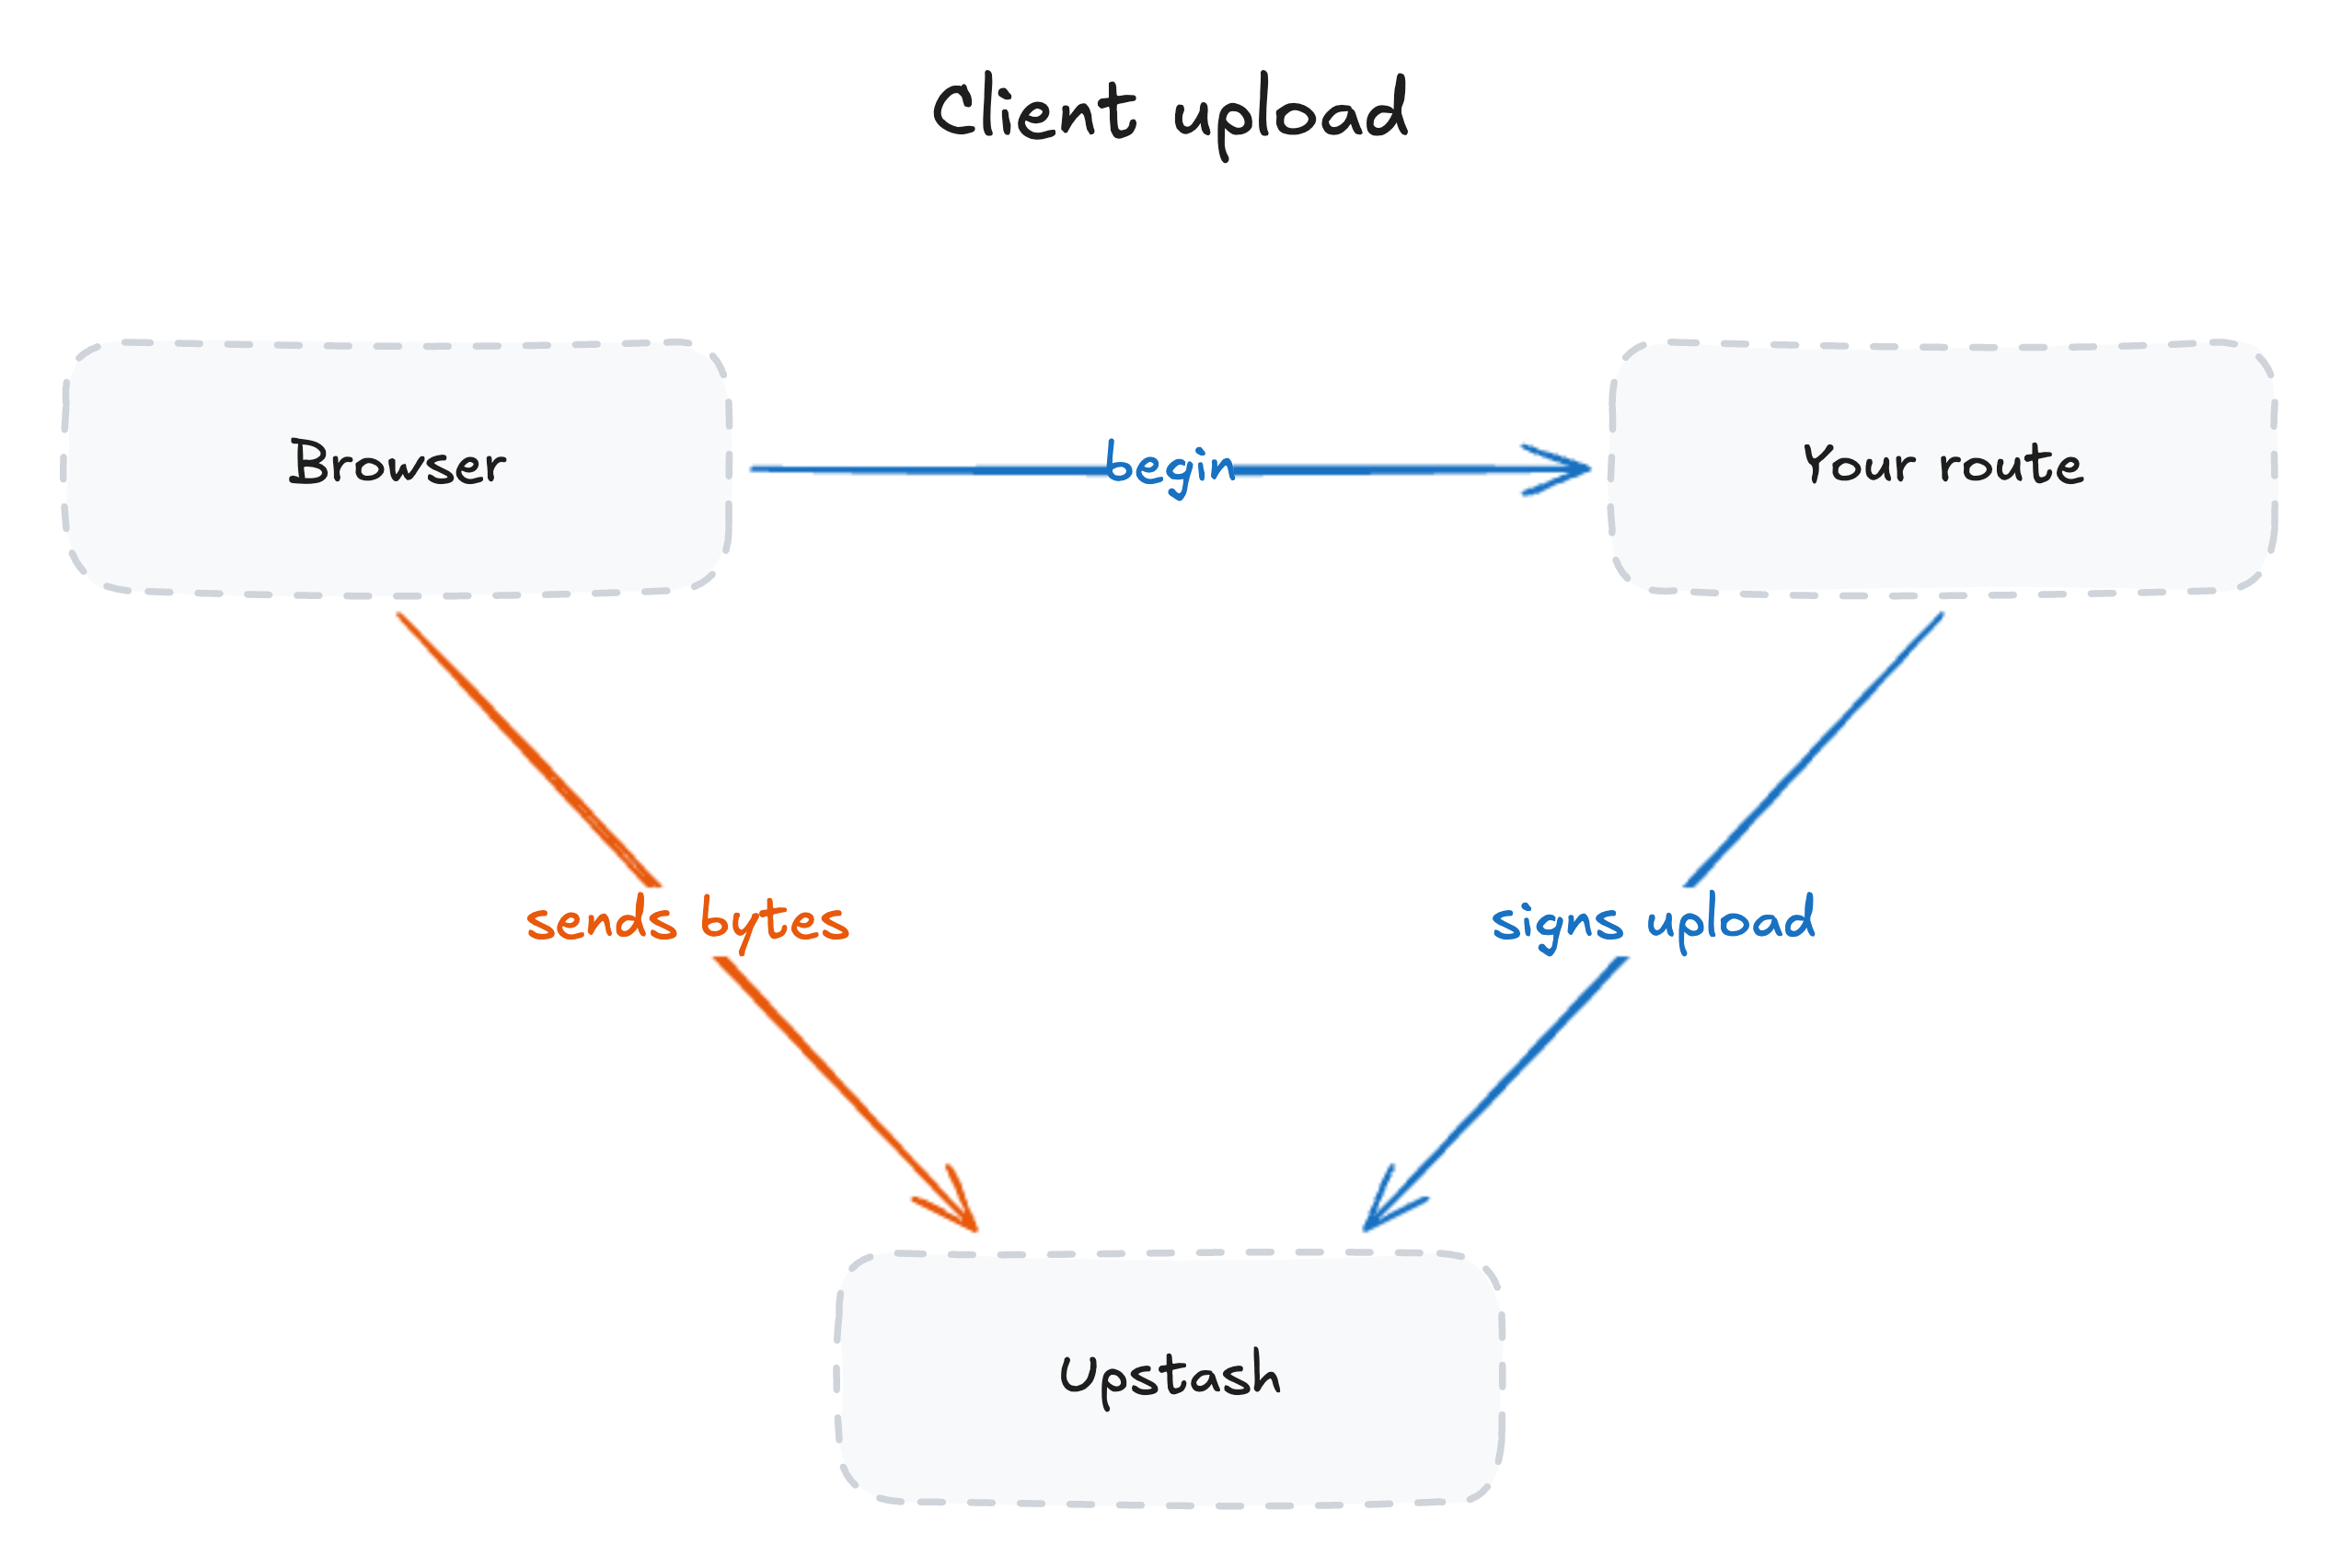
begin phase, before anything is signed, and a completion callback at the end phase, once the object exists. The PUTs in between go to storage, not to you. The phases are listed on Types.
Option names, argument types and framework wiring: TypeScript, Python, Go.
Mounting it
GET and POST at one URL. POST runs the upload phases and GET serves the route’s constraints. The browser client assumes /api/upload and can be pointed anywhere else. It speaks the same protocol to every server SDK, so the frontend does not change with the backend language.
Mounting in other frameworks: TypeScript, Python, Go.
If the bytes have to pass through your app instead, write an ordinary route that calls put and drive it with useServerUpload.
Handler options
Everything except routes, endpoint and context is a default that each route inherits. A route overrides the keys it names, so a handler with five routes states the shared policy once. Constraints merge one level deeper; see Per-route constraints.
The before-upload callback is the only required one. Bad options fail at startup, where they are written: an unparseable multipart size, an invalid route name, an empty routes map, a missing token.
Authorizing an upload
begin, before anything is signed and before any bytes exist. It decides whether the upload happens and where the object goes.
It receives the context value, the route name, the begin request with its headers and cookies, the file the browser declared (name, type and size, before a byte was sent), and the validated input when the route declares a schema.
It returns:
The declared file type is what the object is stored and served as. Whether the bytes match is checked separately; see Byte sniffing.
Paths
. or .. segments. The unique path helper preserves IDs and filenames, including case, underscores, spaces, and Unicode, and adds one random suffix to the final filename. Slashes anywhere in the string are directories, so a prefix can be included as is. The rules are on Unique paths.
A stable path is an overwrite. Two concurrent uploads to the same path race, and the loser’s end can fail with not_found. Use a stable path only when overwriting is the intent.
Metadata
Metadata is signed into the presigned PUT, so the browser cannot add to it or change it. It comes back on the completion callback, is stored on the object, and is readable later withinfo. Same rules as a server-side write: lowercase keys, printable ASCII values. See Metadata.
The key upstash-upload is reserved for the SDK and is refused with invalid_input.
Narrowing per user
Return constraints to tighten the route’s limits for this one upload, for example a smaller max size on a free plan. They can only make the route stricter. See Narrowing per user.Refusing
BlobError (a returned *blob.Error in Go). Nothing is signed and no URL is handed out. The error reaches the browser with its code intact, so a hook can switch on error.code instead of status numbers. The codes are on Errors.
The browser never retries begin, so a callback that writes a row runs once per file.
Recording the upload
end, once the object exists. It receives the completed object’s fields plus everything this route knew about the upload:
What it returns is handed to the browser as
upload.blob.data.
Retries and throws
end leaves an object no callback recorded. See Abandoned uploads.
Handling errors
BlobError or a response to answer with it. Return nothing and the answer is left alone. Written on the handler it is the default for every route; a route with its own replaces it. How a thrown error becomes a response is on Errors.
Context
GET, which serves a public constraints document.
Use it when several routes share one auth check, or when the completion and error callbacks need an authenticated value. With a single route, authorizing inside the before-upload callback and carrying an id in metadata is shorter.
Multiple routes
app/page.tsx
?route=avatar, and the client passes the name instead of a URL.
- Route names must match
/^[A-Za-z_][\w-]*$/, checked when the handler is built. - An unknown name is a 404 that does not list the routes the handler mounts. It still reaches the error callback.
- An upload authorized by one route cannot be completed at another.
- A handler with no routes is itself the route. It is reached with no
?route=. - Two handlers on the same bucket that mount the same route names need an endpoint to tell them apart.
Input and state
app/page.tsx
input, data the browser sends along with the file, and pass state from the before-upload callback to the completion callback.
inputis validated before the before-upload callback runs, and only the parsed value reaches it. A route with no schema refuses anyinputthe browser sends withinvalid_input. Validation failures areinvalid_inputtoo, with the issues joined aspath: message, so a badthreadIdreadsthreadId: Invalid uuid.stateis for values the callback already computed and does not want to look up again. It travels through the browser and is readable in devtools, so put a row id there, never a secret. See The completion token.
The GET endpoint
GET on the route serves its constraints as JSON. That is what fills accept and constraints on the hook, and it lets the hook refuse an oversized file before any request leaves the browser. The server still enforces the same limits at begin. The document and its caching are on Constraints.